Hamel & Shreya's LLM Evals Course: Lesson 1
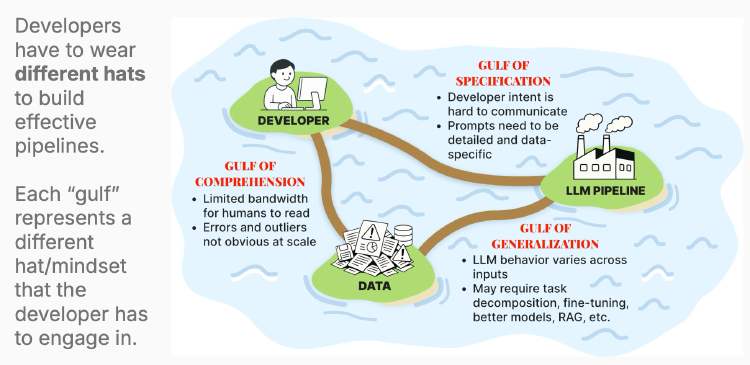
Notes from the first lesson of Parlance Lab's Maven course on evaluating LLM applications - covering the Three Gulfs model and why eval is where most people get stuck.
Notes from the first lesson of Parlance Lab's Maven course on evaluating LLM applications - covering the Three Gulfs model and why eval is where most people get stuck.
I like bits of Brunig's and Mollick's AI frameworks, but neither quite works for me.
A systematic approach to analysing and improving large language model applications through error analysis.
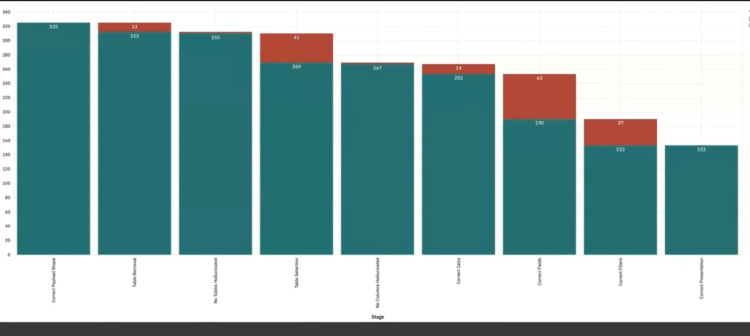
Why evaluation-driven experimentation creates better roadmaps in AI products.
Simon Willison was a guest on Logan Kilpatrick's Google podcast. Topics covered: AI as a 'cyborg enhancement', the non-intuitive challenges of mastering LLM use, and the legitimate need for uncensored language models in fields like journalism.
Exploring AI's role in government: from sanctioned projects to unapproved staff use, and its creeping integration into everyday tools.